Three ScopeDB Design Principles · Part 2
Schema On The Fly
What Is a Data Schema?
A schema gives producers and readers a shared understanding of the data. An application event might always have an observed time, a container identifier, a message, and an application name. A reader can rely on those fields without inspecting every event first.
Other attributes are less predictable. One service records a source file and line number; another adds request details or machine metadata. These fields are useful precisely because they capture context that the common event format did not anticipate.
When Data Schema Becomes a Problem?
A fixed schema works well for the fields everyone agrees on. The difficulty comes when every new piece of context requires a table change before the application can send it. Developers must coordinate database migrations with changes that may be experimental or relevant to only one service.
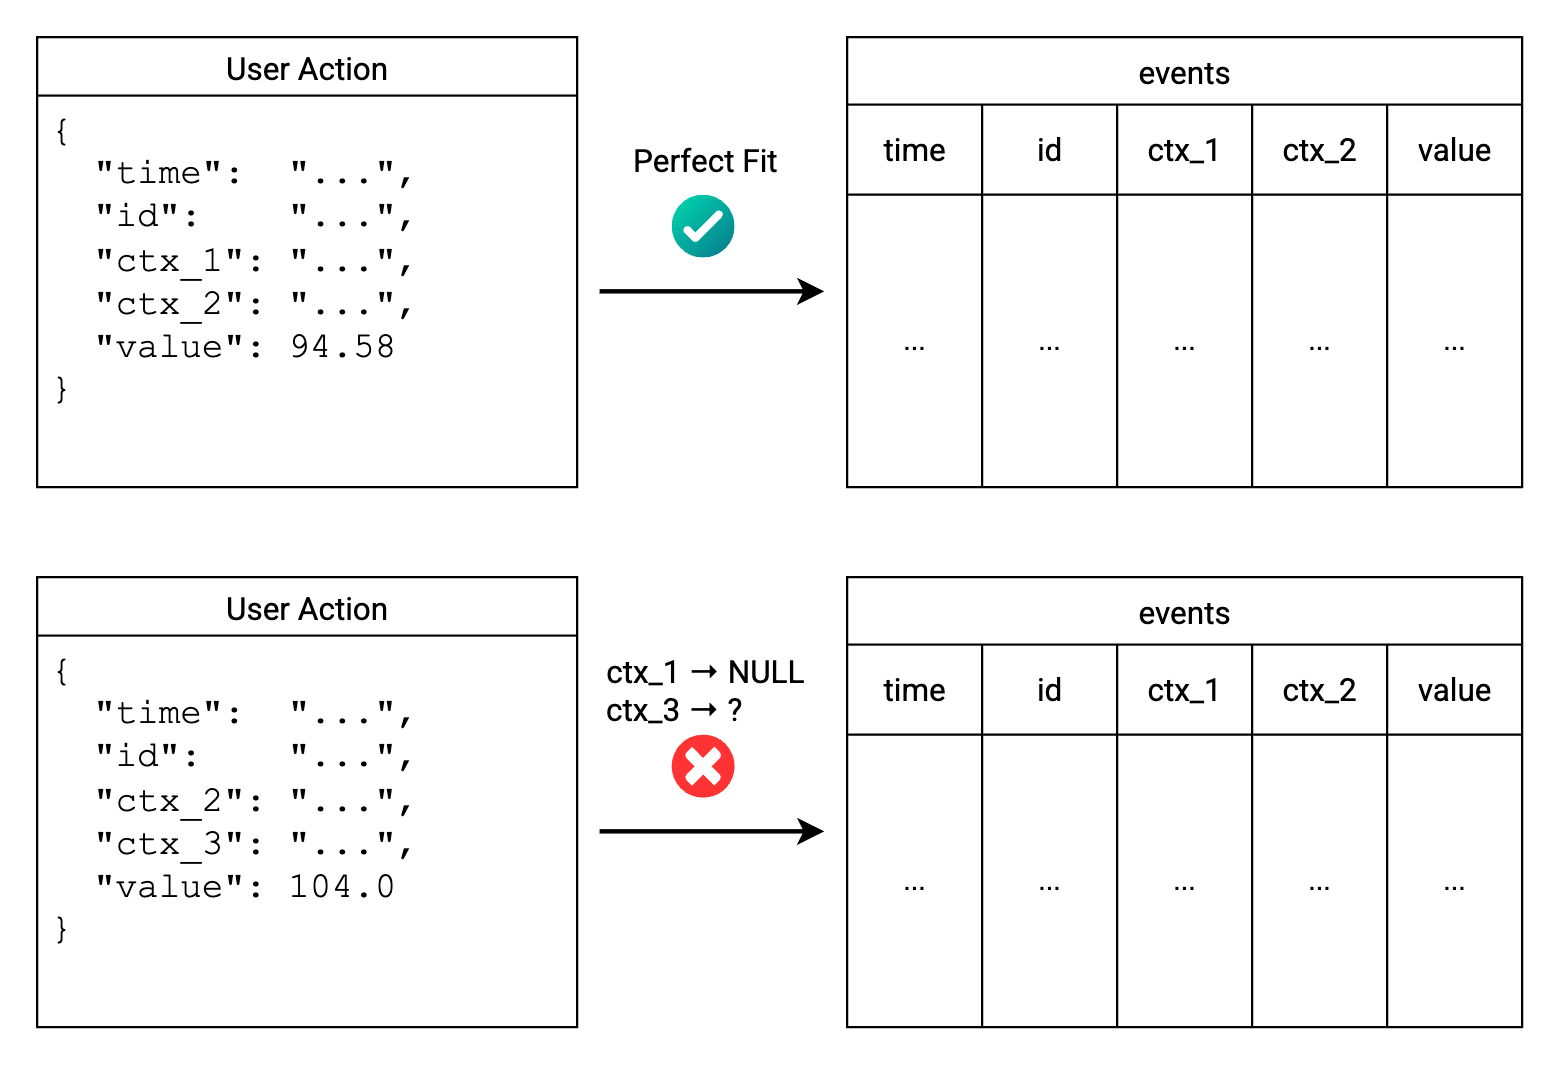
Document databases can accept varying fields without a complete schema upfront. They can also enforce rules: MongoDB supports schema validation, for example. The remaining problem is deciding which conventions readers can depend on. If field names and types drift independently across producers, accepting the data is easier than understanding it.
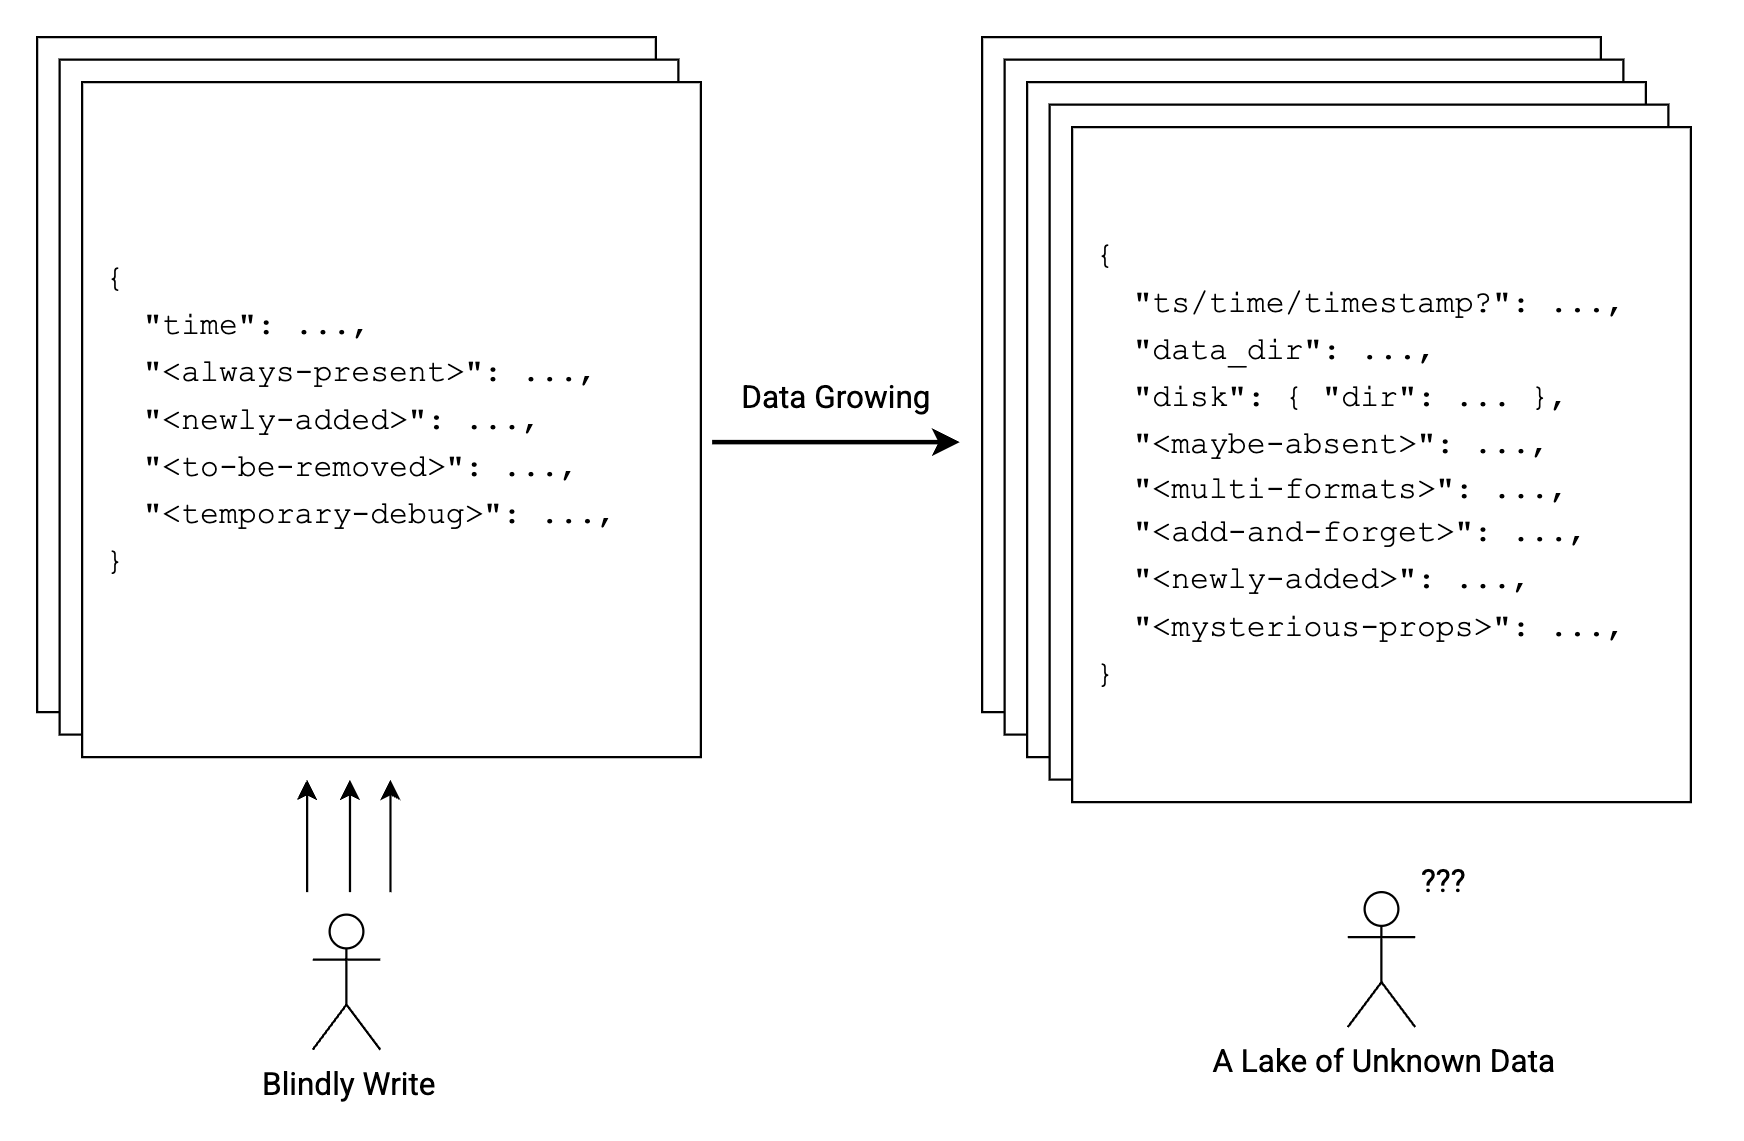
Schema On The Fly: An Ideal Data Schema Solution
ScopeDB combines typed columns with flexible values. An event table can keep time, container_id, message, message_length, and name in dedicated columns, with the rest of the context in an object column named var.
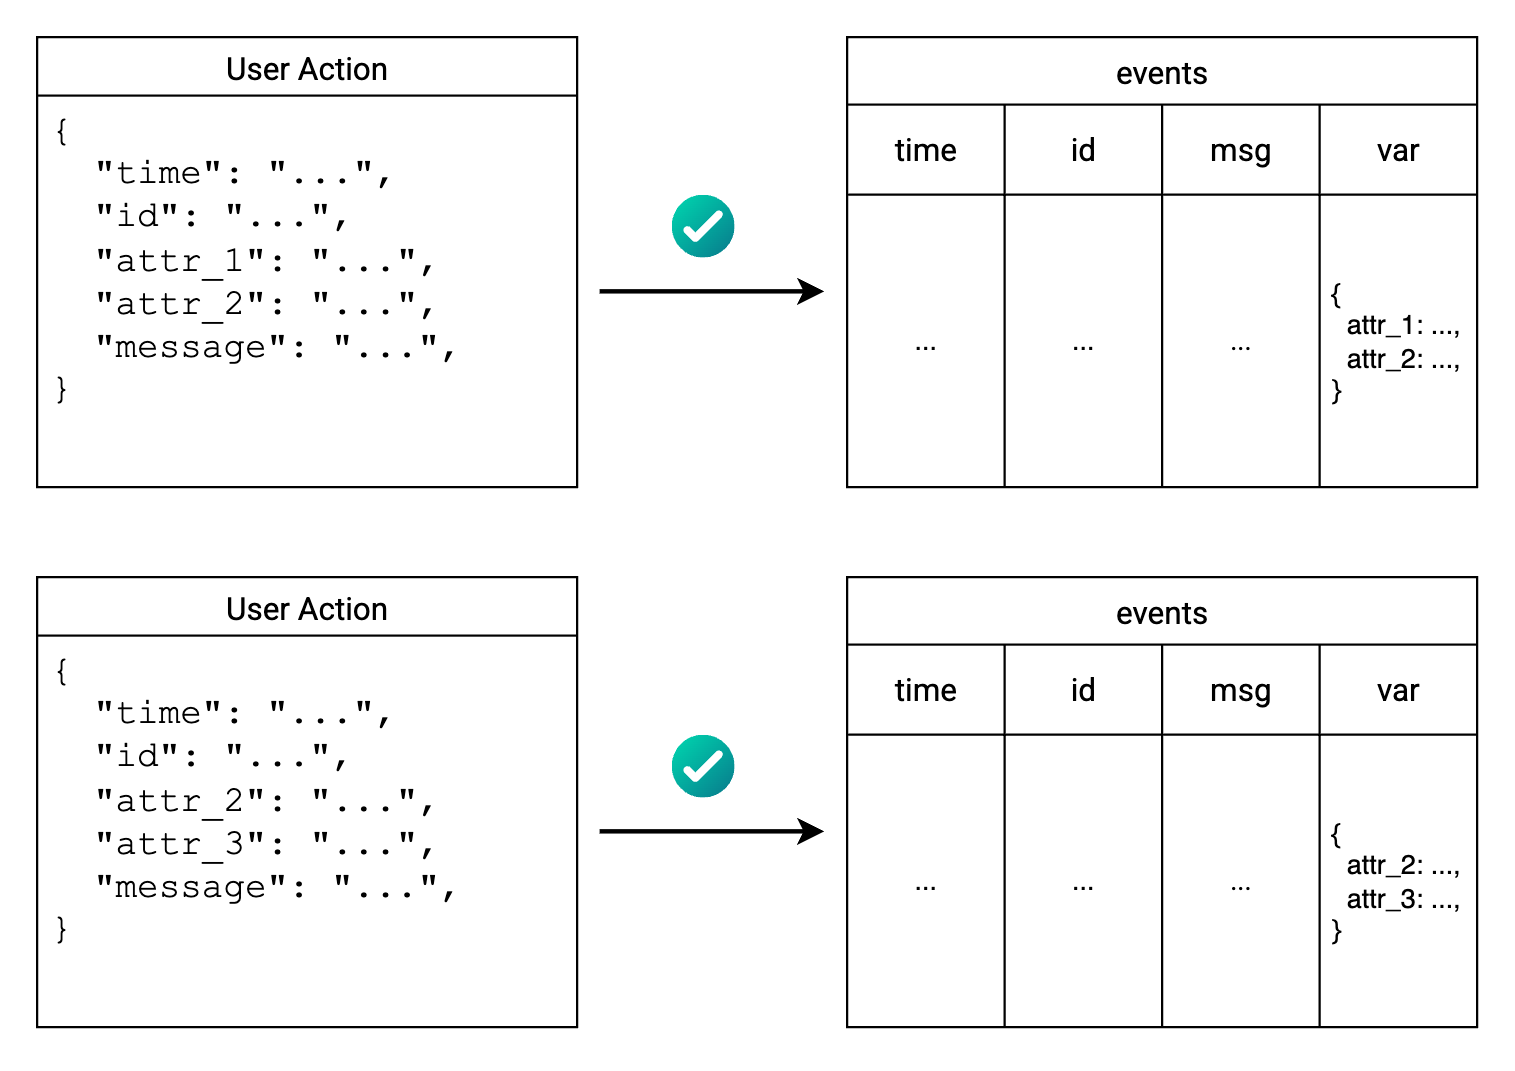
An object maps string keys to values of any supported type, including nested objects and arrays. The table has a stable shape, while the contents of var can differ from row to row.
The important decision is where each field belongs. Keep a field in var while its meaning or type is still changing, it belongs to only a few event sources, or it is mainly useful during investigation. Give it a dedicated column when producers and readers agree on its meaning and type, and shared queries or applications depend on that agreement. Query frequency can justify an index without requiring a new column.
That decision can evolve through writing, querying, and maintaining the same table.
Schema On Write: Reshaping Raw Events
Go, Rust, and JavaScript applications can append rows to the same table. Each producer maps an event's stable fields to table columns and preserves its remaining context in var. The nested fields in that object can vary between events and producers.
Before appending, the application can normalize names, validate timestamps, or exclude health checks. The mapping and validation live with the application that understands the event; Append writes the resulting table rows.
For a small example, take an events table with name string and var object. A service already records its source location in var; now it also records machine.host. It can append this row without changing the table:
{
  "name": "checkout",
  "var": {
    "source": {"file": "pay.go", "line": 42},
    "machine": {"host": "edge-a"}
  }
}
Other producers can keep writing only the context they know. A row without machine.host still fits the same table.
Once the write is committed, both the fixed columns and the new nested attributes are available to queries, regardless of which language produced the event.
Schema On Read: Exploring Variant Data
Readers can use a new attribute before it becomes part of the common schema. For example, this query counts events by application name and the host now recorded inside var:
FROM events
WHERE typeof(var["machine"]["host"]) = 'string'
SELECT name, var["machine"]["host"]::string AS host
GROUP BY name, host AGGREGATE COUNT() AS event_count
ORDER BY event_count DESC
LIMIT 10;
name comes from a fixed column; host comes from the flexible payload. This query includes only events whose nested host is a string, excluding missing values and other types. There is no need to add a column just to ask this question.
For the single row above, the result is:
| name | host | event_count |
|---|---|---|
| checkout | edge-a | 1 |
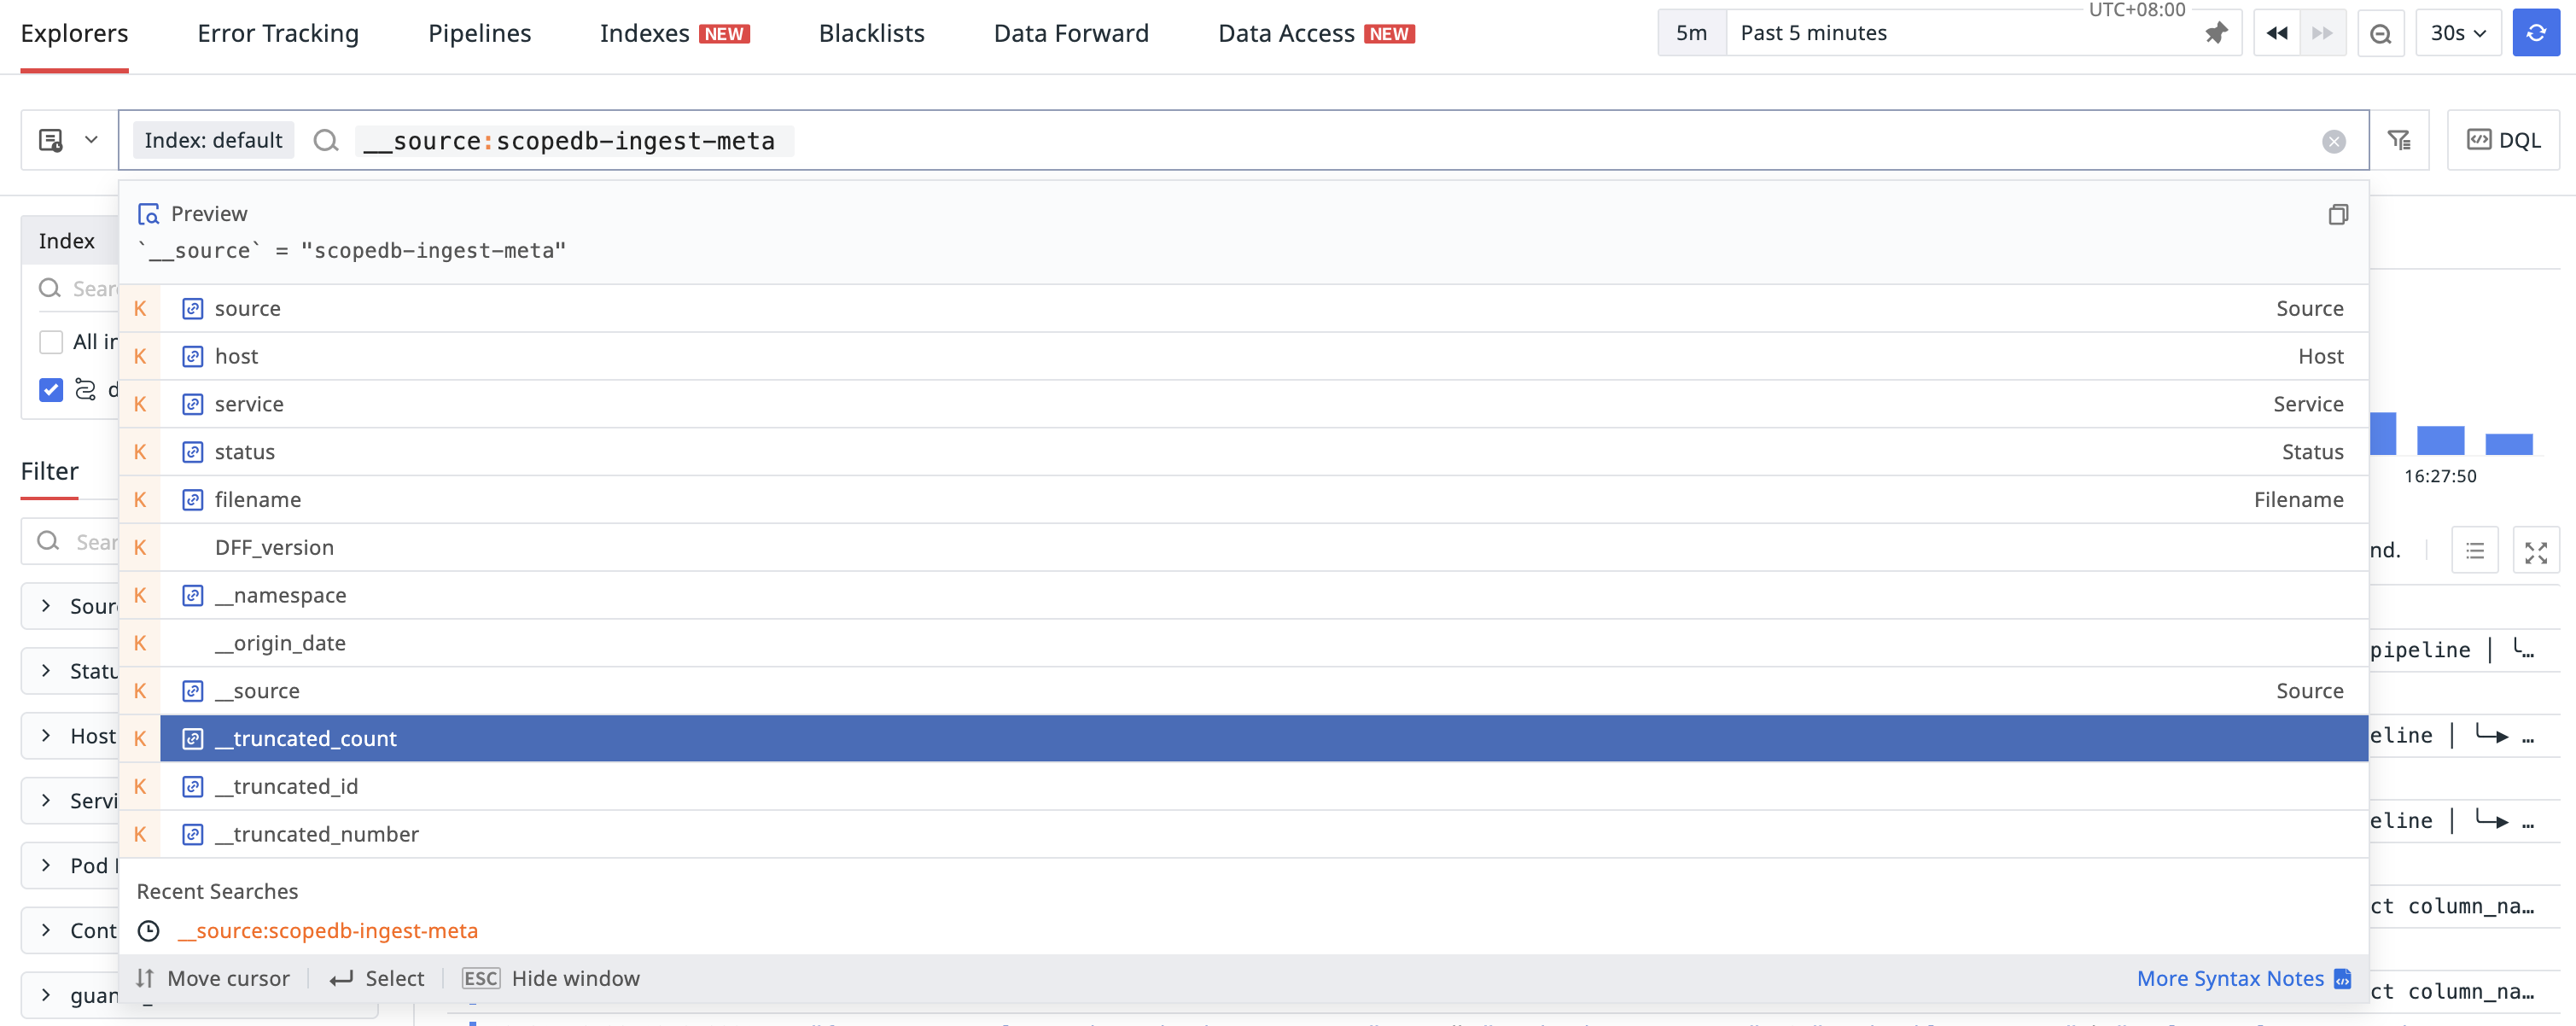
When you do not yet know what an event contains, keys and typeof help inspect its fields and value types. Exploration reveals which attributes are useful, which producers supply them, and where their meanings differ. Those observations can inform a shared schema later.
The following screenshot shows field discovery in an observability application built on ScopeDB.
Schema On Maintenance: Online Schema Evolution
A frequently queried attribute does not automatically need its own column. If machine.host remains specific to a few producers, an index on that nested path can support recurring queries while the field stays in var. A materialized index can store the extracted value so queries do not repeatedly read and extract it from the full object. Existing data is indexed in the background.
A dedicated host column becomes worthwhile when host identity has a stable meaning across producers and is used by shared dashboards, joins, or application code. The column makes that agreement visible in the table definition and gives readers one name and type to rely on.
For the string host names in this example, add the column and let queries prefer it while falling back to the nested value:
ALTER TABLE events ADD COLUMN host string;

FROM events
SELECT name,
  IF(host IS NOT NULL, host, var["machine"]["host"]::string) AS host;
The existing row still returns checkout and edge-a: its new host column is initially NULL, so the query reads var. A new producer can populate the column directly. Adding the column does not rewrite old rows or copy their nested values, which lets producers adopt the shared field gradually.
The distinction matters: indexing improves an access path, while promoting a field establishes a shared data contract. Choose each when the workload calls for it.
Conclusion
Schema On The Fly lets a data model mature with its use. Write new context without waiting for every field to settle, query it to learn what matters, and promote the fields that become common dependencies. Stable columns and flexible objects remain useful together throughout that process.
Follow the data modeling guide to apply this approach to your own events.